2,535inspected sample positions 300 published stills
21useful caption tracks read visual evidence for every film
8paired comparisons 100 individual readings
Sampled visual and caption analysis. No continuous playback or listening pass. Preview timestamps are approximate. This is the newest-100 snapshot, separate from the site’s motion library and the earlier 16-film selection. Scope & evidence →
01 / Different films do different jobs
Start with what the audience needs.
A lesson, a customer account and a launch announcement need different kinds of endings. The collection is grouped by each upload’s dominant editorial job so those differences are easier to compare.
These are study labels, not official categories or performance scores. Counts describe uploads, including related cuts and repeated series.
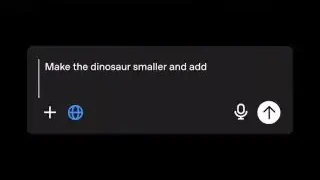
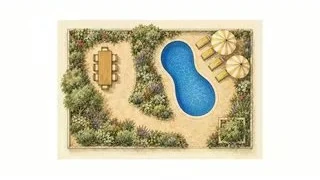
The sketch launch repeats a rough-to-finished relationship across a character, chair, garden and other subjects.
Reading · interpretationBoth structures depend on a starting state the viewer can recognize. The lesson explains how to refine one result; the launch establishes range by repeating the same relationship. Their endings answer different questions: how to improve this image, or what kinds of things the capability might help create.
Proposed use in the all-handsChoose one visible revision when the audience needs to learn a workflow. Use a few matched transformations when the spoken point is breadth. Keep each input visible long enough to compare it with its output; set that duration against the actual recording.
Neither sampled sequence establishes generation time or the complete prompting history.
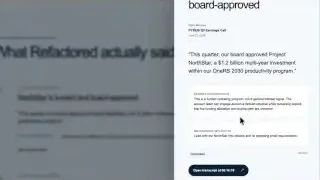
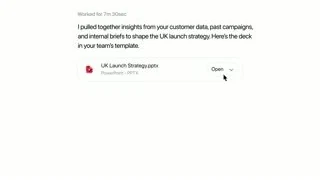
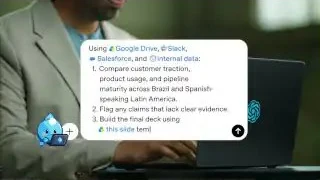
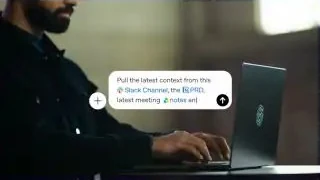
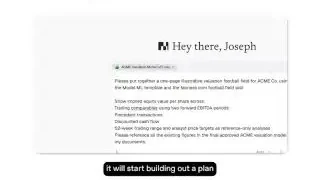
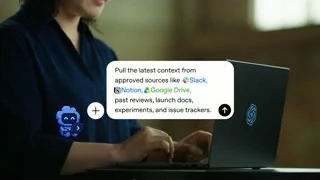
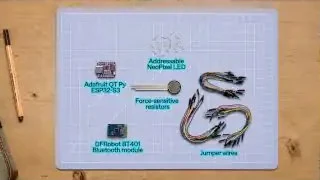
The short launch names several source types in one prompt, then reveals a coherent deck.
Reading · interpretationThe longer film makes the handoffs part of the explanation. The short film puts much of that setup inside the prompt itself. Both give the viewer a recognizable object to follow, even when the application or document type changes.
Proposed use in the all-handsName the project, account or artifact early. Repeat that identity at each application change. Include a handoff only when it advances the spoken argument; a larger number of screens is not evidence of a stronger story.
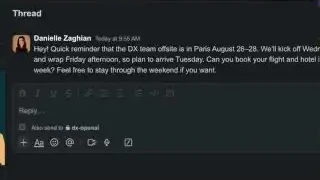
A draft, link or message view does not by itself prove a completed external action.
Comparison 03
The person’s account and the inspectable artifact.
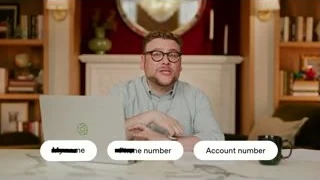
The editing-work short stays on the speaker throughout the inspected samples; no timeline or finished edit is shown.
Reading · interpretationA face and a clear claim can carry a useful testimonial. Adding an artifact changes what the viewer can inspect, but it still does not reproduce the complete process. These two shorts are a practical reminder to distinguish a reported benefit, a presented result and a demonstrated operation.
Proposed use in the all-handsKeep a customer or teammate’s account attributed. If the all-hands asks the audience to believe a specific capability, pair the account with a verified product moment that addresses that claim.
Only sampled burned-in subtitle fragments were available for these two clips; their full spoken arguments were not reconstructed.
Comparison 04
Make the invisible part produce something visible.
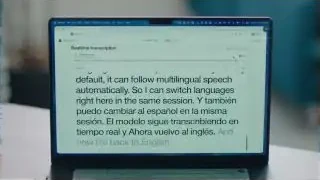
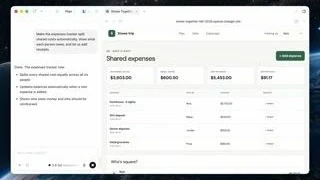
The transcription film places the explanation’s text on a screen next to the speaking presenter.
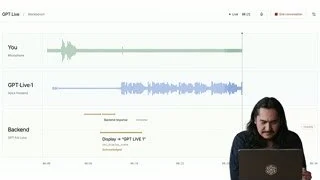
Reading · interpretationThe first example links software to a separate physical response. The second makes the explanation itself the demonstration input. In both, a visible output gives an abstract capability a place in the scene.
Proposed use in the all-handsChoose one output that makes the mechanism legible. Show the input, the relevant processing state and that output without implying that a technical trace proves qualities it cannot show.
These visual readings do not assess audio quality, speech accuracy, interruption handling or latency.
In Harmony keeps a launch-brief task legible inside a stylized office scene, then returns to the shared room.
Reading · interpretationBoth films give the interface a world around it. The customer story’s event makes preparation consequential; the office film’s recurring brief prevents the stylized setting from displacing the task. The people and their setting supply a reason to care about the output.
Proposed use in the all-handsConnect a product result to the work or person it serves. For the all-hands, this may be one original team example after a screen demo, rather than a separate lifestyle montage.
The sampled evidence does not support claims about choreography, soundtrack synchronization or real business impact.
The usage-analysis film includes an on-screen qualification about what activity metrics can establish before building a leadership deck.
Reading · interpretationThese moments tell the viewer what remains for a person to decide. They also sharpen the product story: the useful result is a draft or an informed assessment with a next responsibility, not an unbounded promise of autonomy.
Proposed use in the all-handsIf review, permission or interpretation materially affects the demonstrated result, show it where it occurs in the task. Make the ending match the claim in the actual recording.
An instructional approval step is not a test of the product’s permission enforcement.
Comparison 07
A stable conversation needs different orientation.
Build Hour uses an evaluative question, section titles, demonstrations, a customer case, Q&A cards and resources.
Reading · interpretationThe Forum’s visible structure primarily identifies who is speaking. Build Hour also makes its instructional sections visible. That distinction matters when deciding whether a presentation needs conversational continuity, a navigable argument, or both.
Proposed use in the all-handsFor a long segment, state the question and show recognizable transitions between kinds of evidence. Keep the transition tied to a change in the argument rather than decorating every paragraph.
Each long upload received 72 preview samples. With no captions or listening, this comparison covers macrostructure, not the complete spoken argument.
Comparison 08
One practitioner, or one identity, can hold the collection together.
The templates film carries one racing-team identity from a name and logo into apparel and campaign imagery.
Reading · interpretationA collection becomes easier to follow when something persists across it. Here that continuity is either the maker’s practice or the identity being developed. The individual outputs can vary because the audience has a stable point of reference.
Proposed use in the all-handsChoose what should persist before assembling a showcase: the person, the task, the source object or the visual identity. Remove examples that add variety without developing that thread.
Presented variations do not establish originality, production readiness or representative model quality.
03 / What the evidence suggests
What the expanded sample changes
The newest 100 uploads contain several different editorial jobs. A short announcement makes a capability recognizable. A lesson helps someone attempt a task. A customer account gives an experience a named source. A workflow demonstration carries context into a result. A long discussion depends on an argument that sampled images alone cannot fully recover.
The six labels in this study are editorial judgments about each upload’s dominant job. They are not OpenAI’s official categories or a ranking of effectiveness. The collection is concentrated between July 24 and September 18, 2026, with repeated series and related cuts. It describes this release period; it does not represent a balanced year of the channel.
1. The clearest small story is a recognizable change
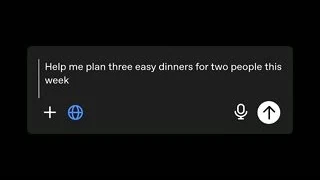
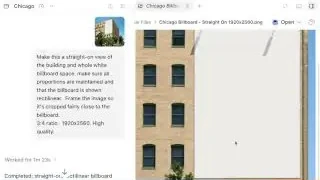
The coloring-page lesson makes one revision request and shows a changed composition. The sketch announcement repeats a rough-to-finished relationship across several subjects. The font-playground short gives the viewer successive states of a single creative interface.
These examples suggest a useful planning question: what will the audience be able to compare? A recognizable starting state and a specific changed state give a product segment an argument. A polished result alone may show quality, but it leaves more of the transformation for the viewer to infer.
2. Cross-app stories need a persistent object
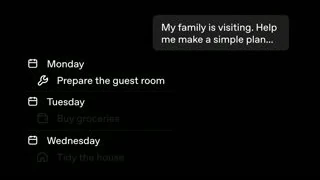
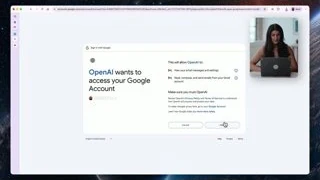
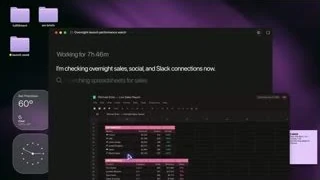
In account research and outreach, the customer context survives the move from a source document into a brief, an email draft, a deck and a team thread. In the daily CFO briefing, the progression from phone to analysis, spreadsheet and presentation changes how the work can be used. The short deck announcement compresses the setup by naming the mixed inputs inside one prompt.
The practical lesson is to preserve the task’s identity across the edit. A familiar account name, document title or unresolved question helps explain why the next application appears. Without that thread, a workflow can become a tour of available integrations.
3. The strongest ending for a work demo may be a handoff
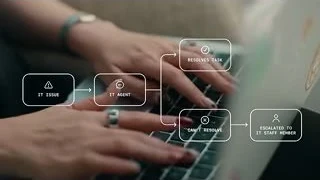
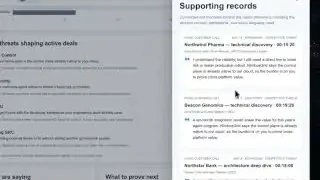
Quarter-end reconciliation moves from findings and release conditions into a finance conversation. Revenue intelligence connects a report, supporting records and recommendations to a workplace thread. Pipeline intelligence extends an identified gap into plans and coordination material.
These are more specific endings than another dashboard beauty shot. They answer where the information goes next. They still need careful language: a visible draft, plan or message is evidence of the presented artifact, not proof that every real-world action was completed.
4. Testimony, artifact and operation are different kinds of evidence
The editing-work short remains on the speaker throughout the inspected samples. The creative-detail short and font-playground short add objects the viewer can inspect. The Model ML story goes further into a request, plan, chart and editable presentation, while keeping the efficiency assessment attributed to the customer.
Each format can be useful. The distinction is what the ending supports. An account establishes what someone reports. An artifact exposes a result. A visible operation can explain a mechanism. None automatically establishes representative reliability, measured speed or business impact.
5. Teaching films make the next responsibility visible
The customer-meeting lesson includes review and approval after follow-up preparation. The strategy-deck lesson separates gathering context, choosing the story and building the artifact. The usage-analysis film visibly qualifies what activity statistics can establish before turning the analysis into a leadership deck.
These steps help define completion. The person has something useful to inspect, approve or interpret. For an all-hands segment, show that responsibility when it affects the claim; it is part of the task’s ending.
6. Human stories give the screen a reason to appear
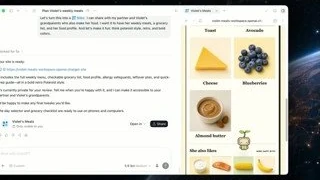
The small-business film places device use inside preparation for a public event. The two-brothers film follows people through city, café, workplace and travel settings. Birding Pal takes a prototype from the workbench back outdoors.
The interface enters because the person is trying to do something. The return to that activity gives the interaction meaning. Borrow the relationship between task and consequence; do not treat the source footage, customer lives or brand identity as assets for a new presentation.
7. Repeated series are useful comparisons, not independent votes
The channel’s related workflow batches use similar opening promises, work surfaces and closing messages. The creator interviews also appear in longer conversations and narrower vertical clips. Tom Krcha’s longer account, the creative-detail short and the font-playground short visibly share a practitioner, setting and examples.
That repetition is useful for studying how an argument changes with format. It does not mean three uploads are three independent demonstrations of an editorial rule. The genre counts describe uploads, and no audience-retention or engagement evidence was collected.
8. Longer formats expose the limit of a visual sample
The Forum panel is visually stable through much of its 39-minute runtime. Build Hour changes among section cards, demonstrations, customer slides and Q&A over roughly 55 minutes. The latter also has official chapter metadata.
The visual evidence supports a comparison of orientation and macrostructure. It cannot support a detailed account of either spoken argument without captions or listening. These two readings carry that narrower scope explicitly. Source runtime is reported for context and is never counted as time watched.
04 / The complete frozen cohort
One hundred individual readings.
Newest first. Each reading separates observed moments, interpretation, a proposed takeaway and the limits of its evidence.
Start with one substantial point in the actual talking-head recording. Write the audience’s question, the claim being made, a starting state and the result the audience should inspect. Choose a reference because its structure serves that point.
If the recording needs to…
Useful structure
What the storyboard should contain
Explain a product improvement
Recognizable state → one meaningful change → inspection
The same real task before and after, with the relevant difference legible
Explain work across applications
Specific request → carried context → destination
A persistent project or artifact identity at each handoff
The person’s actual account, with a verified example where the claim needs it
Teach a new workflow
Outcome preview → steps → revision or review
Enough setup to understand the action and the person’s next responsibility
Show a range of possibilities
Stable person or identity → distinct examples → return
A reason each example belongs, rather than a collection of attractive outputs
Discuss an uncertain or unfinished result
Question → current evidence → unresolved decision
The limit stated where it affects the audience’s conclusion
The storyboard worksheet is the place to make that choice concrete. Record the reference title or URL in the demo notes when using a film from this new cohort; the worksheet’s original reference picker still contains the earlier 16-film selection.
Give the ending the same scope as the spoken claim
A draft can support a claim about getting to a useful starting point. An inspected calculation can support a narrower claim about the shown example. A customer account can support an attributed experience. Choose the ending evidence before adding decorative motion, and verify the current Poe interface and behavior before planning a product capture.
The source timecodes locate observed passages. They are not prescribed cut points, official timing rules or a recommended edit list. Set holds, transitions and demo length against the supplied recording’s actual speech and pauses.
Preserve the two playback assets
The supplied talking head remains separate from the generated presentation video. The presentation begins first and uses a recognizable content transition to cue the manual OBS switch. Record the cue and measured playback offset; do not assume an instantaneous switch or automatic synchronization.
Keep spoken narration out of the presentation video. Its ending must land while the talking head’s recorded wave and pause are still playing, leaving time to mute and turn off video in Zoom. If the footage lacks that ending buffer, raise it in the storyboard review.
Bring the timed transcript, visuals, demo list, references, cue, offset, ending buffer and export requirements to the single planned storyboard review. This research chapter proposes structures; it is not an approved production storyboard.
This is a frozen study of the newest 100 distinct public uploads found across the official channel’s Videos, Shorts and Live listings on September 18, 2026. The listings contained 805 distinct IDs. Publication metadata was checked for 125 recent candidates, and the cohort was ordered by official publication timestamp in UTC. Equal timestamps use the Videos listing position, then the video ID.
The selected uploads run from July 24 through September 18, 2026: 92 from Videos and eight from Shorts. No Live-tab upload falls inside this newest-100 cohort. The scope is the public listing snapshot, not a historical archive of deleted, private or unlisted material; there was no independent terminal-pagination audit.
Evidence and review depth
All 100 readings use inspected visual evidence. In total, 2,535 sampled positions were inspected. Forty-two uploads were sampled from newly downloaded low-resolution video, 16 reused retained decoded-frame evidence, and 42 used publicly accessible YouTube storyboard previews. One of those preview sets used fresh metadata; the others used retained, identity-checked metadata.
Short uploads generally received 24 positions distributed across their runtime. New video extractions also received a near-end sample when available. The two uploads longer than ten minutes received 72 preview positions each. Retained evidence was selected from its existing sample grid; one short film had 21 available positions. These are coverage samples, not detected shots or a cut-by-cut annotation.
Twenty-one useful caption tracks were read in full. The remaining readings use visual evidence, any legible on-screen text, and identified source metadata. A sampled subtitle fragment does not count as a reviewed caption track. Caption availability and the visual basis are stated on each reading.
No continuous playback or listening pass is claimed. The study does not assess soundtrack, vocal delivery, exact motion, edit rhythm, response latency or audience retention. The source runtimes sum to 4 hours 41 minutes 52 seconds; that is the size of the source collection, not viewing time.
How to read the timecodes
Fresh frame samples use decoded video timestamps, apart from the separately requested near-end sample. Retained frames keep their recorded clocks. Public storyboard preview times are estimates from the preview index and metadata frame rate and can drift from native video timestamps. All displayed links locate approximate passages; none is a claimed cut boundary.
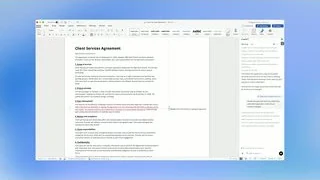
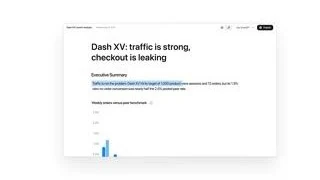
Each page publishes three small stills chosen from the reviewed evidence. A nearby sample may illustrate a passage rather than the exact instant described. Captions identify what is visible in the published still; the reading explains the broader observed sequence. Use the linked official video for full-resolution inspection, motion and sound.
Observation, interpretation and proposed use
The timecoded notes describe the inspected evidence. The introductory reading and named story pattern are interpretations. The all-hands takeaway is a proposed adaptation. The six genre labels describe each upload’s dominant editorial job and are assigned for this study, not taken from an official taxonomy.
Related edits and repeated series remain separate uploads in the count. They are not independent campaigns, experiments or votes for a universal storytelling rule. No performance ranking is inferred from how often a structure appears.
Relationship to the earlier chapter
The earlier 16-film study remains available with its deeper selected readings, six structures and storyboard worksheet. Six of those films also appear here. Together the two storytelling selections cover 110 distinct video IDs; their sample counts and review depth remain separately reported. This newest-100 study is also distinct from the site’s existing motion-reference library.
Small evidence, disposable working data
Source downloads and preview fragments were processed one upload at a time in temporary directories and removed after each video. Public pages contain compact selected stills, original commentary and source links. They do not contain source video downloads, full caption tracks, private working logs or signed media URLs. Publication staging is disposable and is removed after the live release is verified.
The structured ledger records the frozen cohort, source links, review basis and readings. The Markdown edition contains the same written research for reference. Source films, frames and marks remain the property of their respective owners; these small excerpts accompany commentary and are not a cleared production asset library.